By Seth Earley, Founder & CEO, Earley Information Science
────────────────────────────────────
Published: August 2026 | Article 1 of 10 in the *Scaling GenAI* Series
Last Updated: August 2026 | Version 1.1
────────────────────────────────────
Who This Is For: C-suite executives, VP/Directors of Digital Transformation, AI/ML leaders, and Enterprise Architects responsible for scaling GenAI initiatives beyond pilot stage. Also valuable for KM leaders and Chief Data Officers tasked with enabling AI-ready content infrastructure.
Prerequisites: Basic familiarity with GenAI concepts and enterprise AI pilot projects.
────────────────────────────────────
This is Part 1 of a three-part series on scaling enterprise AI. Read Part 2: Why RAG Fails Without Information Architecture and Part 3: Governance That Enables Iteration
Your AI pilot worked. The board approved expansion. And then the initiative stalled.
Across large organizations, this pattern has become consistent enough to deserve its own name: the Pilot Paradox. The very conditions that make a proof of concept succeed are the conditions that make enterprise deployment fail. The pilot didn't just succeed despite limited scope — it succeeded because of it. And therein lies the problem.
Research from Harvard Business Review Analytic Services puts a number on the blind spot. When surveyed about barriers to implementing generative AI, enterprise decision-makers ranked the inability to access and leverage data last among fourteen obstacles — cited by only 16% of respondents. Yet once those same organizations attempted to scale, 39% identified data issues as their top challenge. The barrier was invisible until they walked into it.
This article examines why the gap between pilot and production is not a linear increase in effort but an exponential increase in coordination complexity — and what that means for how organizations need to plan and invest in AI.
Why Pilots Succeed by Avoiding Enterprise Reality
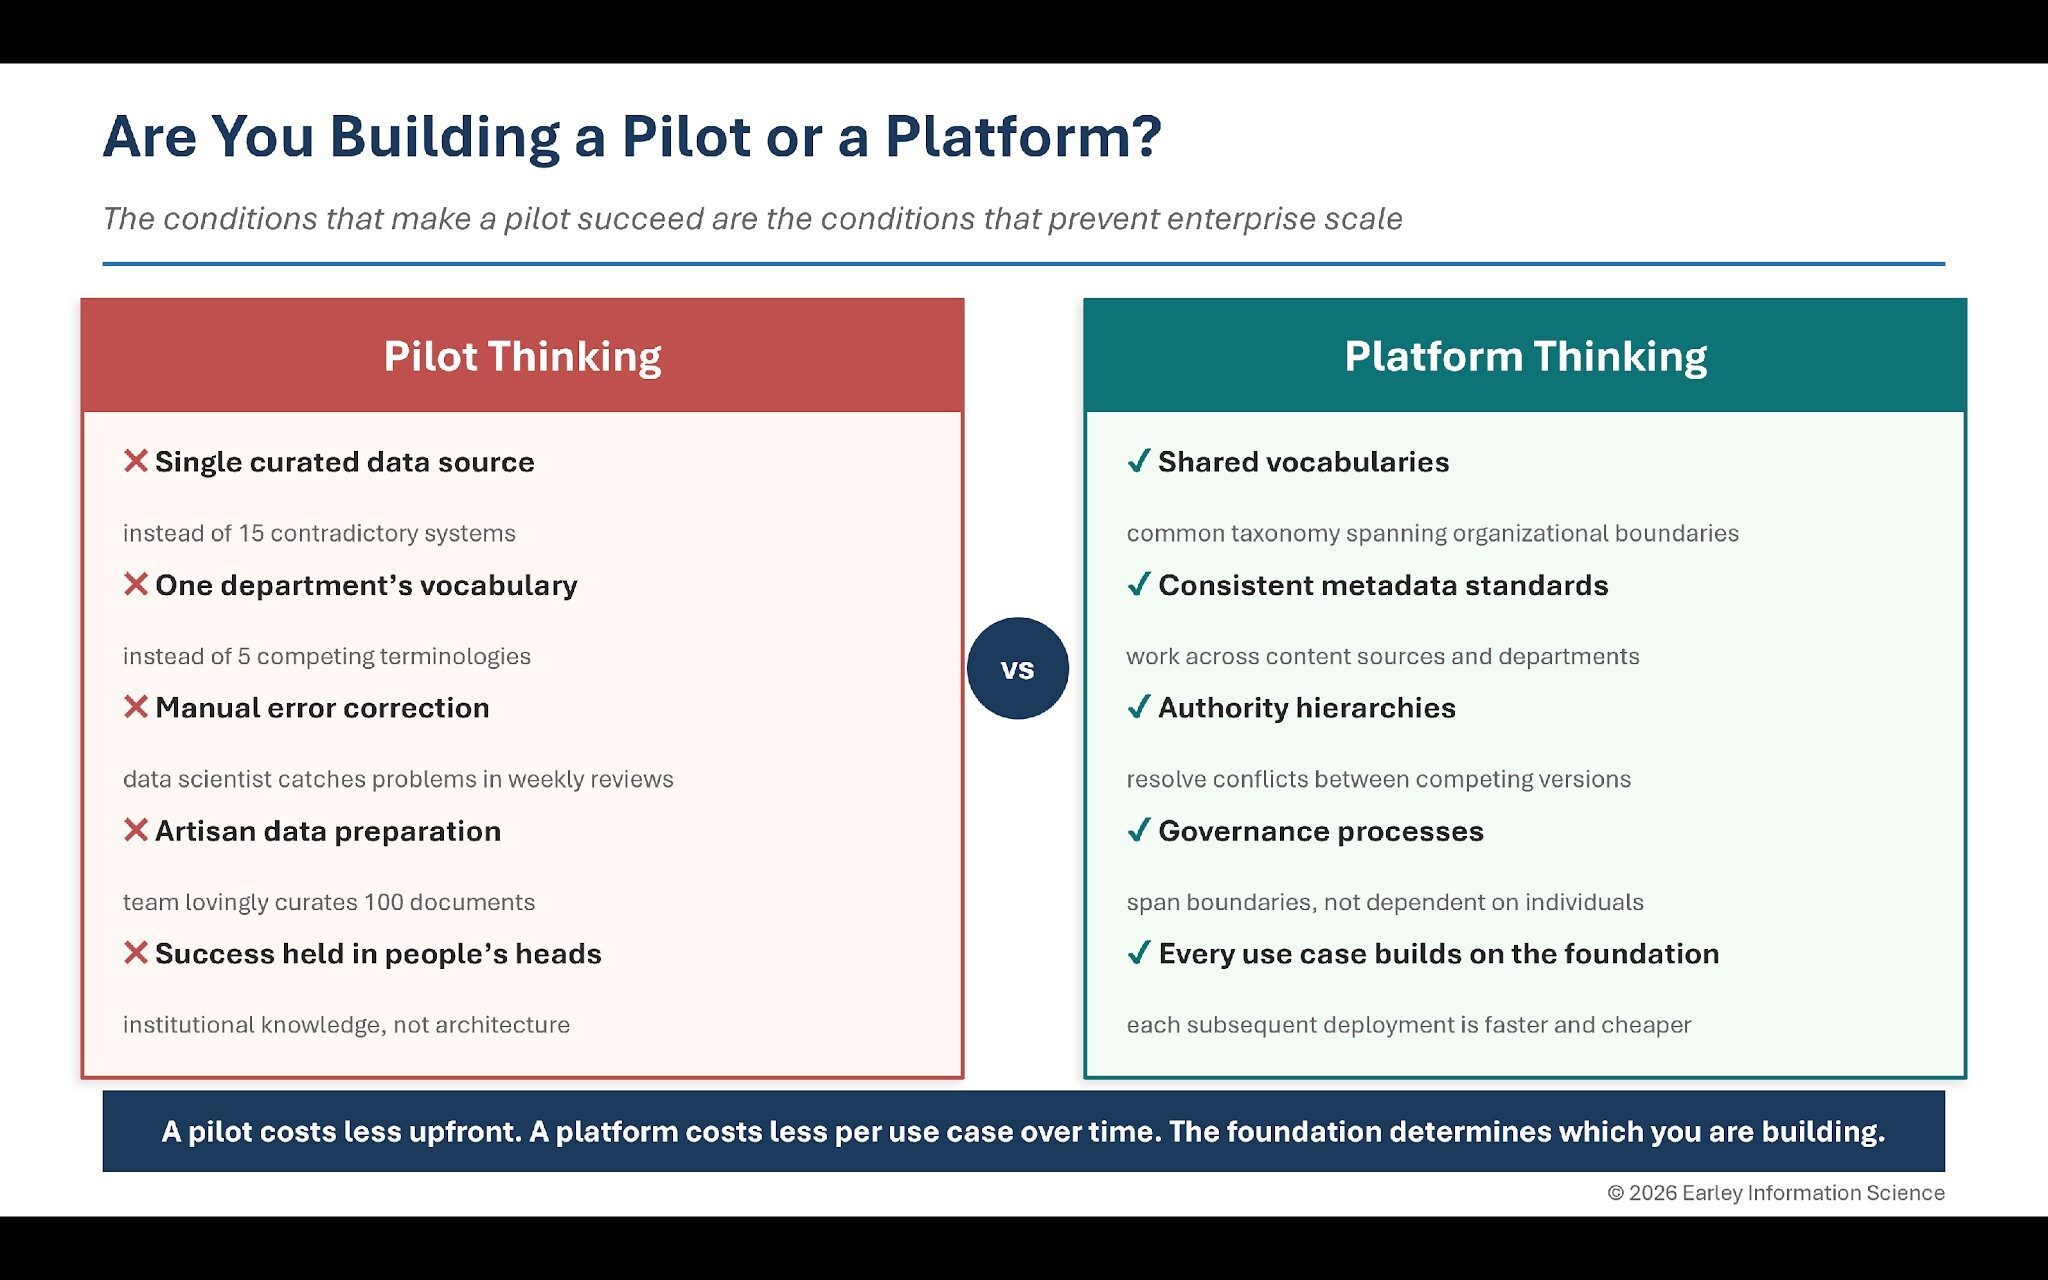
Every successful proof of concept operates under conditions that exist nowhere else in the organization. A single curated data source instead of fifteen contradictory systems. One department's shared vocabulary instead of five competing terminologies. A skilled data team quietly correcting errors that automated processes would need to handle at scale across millions of queries. Success metrics defined by one stakeholder group rather than contested across ten.
The pilot succeeds because humans are compensating for missing infrastructure — and doing so invisibly. A data scientist spends forty hours cleaning a hundred documents. A subject matter expert catches wrong answers in weekly reviews. Everyone uses the same terminology because they sit in the same room. None of this scales, and none of it shows up in the pilot's cost model.
The standard guidance for technology implementation is to start small, get a quick win, then scale up. The problem with this advice is that scaling up is not a larger version of the pilot. It is a structurally different category of problem.
The Integration Math: Why Complexity Multiplies
Most leaders assume scaling is roughly proportional: if a system works for fifty users in one department, multiplying resources should serve five thousand users across ten departments. This assumption treats each dimension of growth — more departments, more use cases, more content sources, more users — as independent. In practice, these dimensions interact multiplicatively.
A typical pilot involves one department, two use cases, two content sources, and fifty users. A typical enterprise deployment involves ten departments, twenty-five use cases, twenty content sources, and five thousand users. Each individual dimension grows by roughly an order of magnitude. If growth were additive, the enterprise deployment would require ten to a hundred times the resources. That is what most planning budgets assume. The actual complexity is not in the individual dimensions — it is in the connections between them.
Cross-department alignment — reconciling terminology, taxonomy, and governance priorities across organizational units — grows as a combinatorial function. One department requires zero alignment challenges. Five departments require ten. Ten departments require forty-five. Content source integration follows the same pattern: two sources require one schema mapping; twenty sources require up to 190 potential schema conflicts. Use case and content source combinations multiply further. Even with 40% relevance overlap, which is typical in enterprise environments, twenty-five use cases across twenty content sources produce roughly two hundred integration points. Governance touchpoints — approval workflows, ownership boundaries, escalation paths — add another hundred or more.
The arithmetic is striking. A pilot with one department, two use cases, and two content sources has roughly seven integration points to manage. An enterprise deployment with ten departments, twenty-five use cases, and twenty content sources has five hundred or more. That is a seventy-fold increase in coordination complexity before accounting for the hundred-fold increase in users.
Why This Changes the Planning Calculus
The pilot succeeded because one team could hold all seven integration points in their heads. At enterprise scale, that institutional knowledge must be embedded in architecture, governance, and process — or the system collapses under its own weight.
This is why proportional resource scaling does not work. A combinatorial coordination problem cannot be solved by hiring more people. It can only be solved by building the infrastructure that makes coordination manageable: shared vocabularies that span departmental boundaries, consistent metadata standards that work across content sources, and authority hierarchies that resolve conflicts when different systems produce different answers. This is the coordination layer that transforms a collection of departmental tools into an enterprise capability.
The Blind Spot: Why Organizations Don't See It Coming
The research finding is instructive precisely because it is so consistent. More than half of the organizations surveyed rated their data foundation readiness below the midpoint of a ten-point scale. Yet before attempting to scale, they did not view data quality as a meaningful obstacle.
The explanation is structural. During the pilot, manual curation masks data quality problems. The team compensates for missing infrastructure without recognizing that compensation as a cost. When that compensation must scale, the cost becomes visible — but by then the organization has committed budget, set stakeholder expectations, and made promises based on pilot performance that assumed conditions which no longer exist.
This is not a failure of due diligence in the conventional sense. It is a failure of the mental model that treats enterprise AI deployment as a linear extension of a successful proof of concept. The pilot and the enterprise deployment are different categories of problem, not different sizes of the same one.
What Successful Organizations Do Differently
The organizations that navigate this transition effectively share a common characteristic: they plan for integration complexity from the beginning rather than after it surfaces.
Before expanding beyond a single department, they invest in shared infrastructure — a common taxonomy that spans departmental boundaries, metadata standards that work across content sources, and authority hierarchies that resolve conflicts between competing versions of the same information. This coordination layer is what makes subsequent deployments faster and cheaper rather than progressively more expensive.
They also build feedback and error-correction processes before deployment rather than after the first crisis. Every AI system will produce errors. The question is whether those errors get detected, diagnosed, and corrected systematically, or whether they accumulate until users lose confidence in the system entirely.
Perhaps most importantly, they distinguish between the technology layer and the content infrastructure layer. Models, embeddings, and vector databases evolve rapidly and costs decline over time. Metadata, taxonomy, content models, and authority structures compound in value. Every use case built on a shared content foundation is faster and cheaper than the first. Organizations that recognize this invest in the foundation as a platform rather than treating each AI initiative as an independent project with its own data handling.
The Question That Reframes the Investment
The question most organizations ask when a pilot succeeds is: how do we scale this? The more useful question is: are we building a pilot or a platform?
A pilot solves one problem in one department with manual curation and institutional knowledge held by individuals. A platform builds the integration infrastructure that makes every subsequent use case faster, cheaper, and more reliable. The pilot costs less upfront. The platform costs less per use case over time — and is the only approach that remains viable as integration complexity grows.
At seven integration points, manual coordination works. At five hundred, only architecture works. The foundation built today determines which answer applies to the organization tomorrow.
Continue reading: Part 2: Why RAG Fails Without Information Architecture | Part 3: Governance That Enables Iteration
Read the original version of this article on VKTR.